Transaction Reconciliation System

Turning millions of financial transactions into a system that could be trusted.

A financial reconciliation platform built to automate the ingestion, processing, matching, and investigation of transactions across banking channels and external transaction sources — designed to answer, at scale, the question every digital bank eventually has to answer: can we prove that every transaction recorded by one system is accurately accounted for everywhere else it touches?

Reconciliation built for financial transaction volume.

Integrated with mobile banking, ATM, and core banking systems.
Automated identification of commissions, cash retracts, and cash refills.
Configurable reconciliation modules with dynamic data mapping.
Reduced manual investigation by approximately 85%.
Deployed across seven commercial banks.
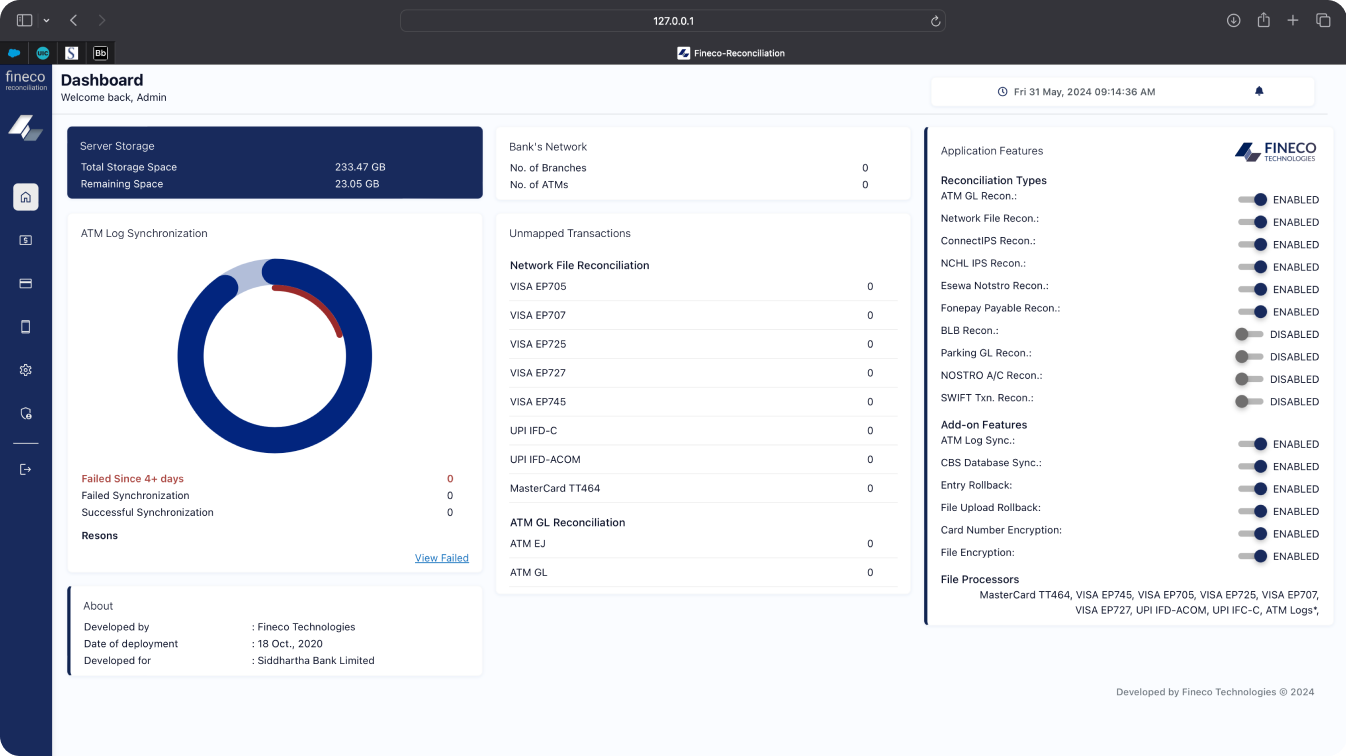
Transaction Reconciliation System interface

Why this system was needed.

As banks moved transactions from physical branches to digital and self-service channels, transaction volume grew fast — and so did the number of systems generating records of the same event.

ATM networks, mobile banking, core banking, and payment processors each produced their own version of a transaction, often in incompatible formats.

That created operational questions that used to be cheap to answer and were quickly becoming expensive:

  • Did the transaction actually complete?
  • Did the customer receive the expected amount?
  • Was a transaction recorded twice?
  • Was a commission charged correctly?
  • Was cash retracted after being dispensed?
  • Which customer account does this transaction belong to?
  • Can it be traced back to its original source?

The hard part wasn't comparing two files.

The real challenge was building an engine that could ingest large volumes of financial records from different systems and formats while preserving data integrity end to end.

An ATM log, for example, could contain fields with no direct equivalent in the corresponding core banking record. The system therefore needed to normalize different sources without losing the evidence required to investigate them later.

01
Ingest multiple transaction sources

Records needed to arrive from banking channels, external sources, files, and direct system integrations without forcing every source into the same ingestion mechanism.

02
Normalize different transaction formats

Different schemas and transaction formats needed to be transformed into a common model without losing source-specific information.

03
Match the same event across systems

The engine needed to identify which records represented the same transaction even when source systems described that event differently.

04
Preserve the original evidence

Raw source records had to remain available for audit and investigation even after the transaction had been transformed and reconciled.

05
Prevent duplicates and preserve correctness

A record could not be accidentally ingested, processed, or matched twice as files were retried or integrations recovered from failures.

06
Scale as transaction volume increased

Reconciliation and investigation needed to remain responsive as transaction history and daily throughput continued to grow.

In practice, the system needed to behave less like a CRUD application and more like a transaction-processing engine.

Architecture and transaction-processing infrastructure.

I was responsible for the architecture and development of the platform, not just individual features.

Designing the transaction-processing architecture and data model for high-volume financial records.
Building ingestion and processing workflows, including automated ATM log extraction.
Designing transaction matching, reconciliation, and duplicate-prevention logic.
Designing the dynamic data-mapping system used to onboard new sources.
Integrating directly with core banking systems beyond file-based imports.
Implementing transaction-related business rules including commissions, retracts, and refills.
Handling encryption and secure storage of sensitive financial information.
Designing the platform's modular reconciliation components.

The central architectural responsibility was making sure a transaction could be traced from its original source through to its final reconciliation state without losing that chain.

Where the complexity actually lived.

Challenge 01
Volume as a first-class design constraint

At 5M+ transactions per day, this wasn't a script that loaded two files into memory and compared them. It had to continuously ingest, store, identify, and reconcile records without the database becoming the bottleneck.

Financial records also couldn't simply be archived away. They needed to remain live, queryable, and traceable for regulatory and investigative reasons.

I designed a middleware layer between ingestion and storage that could break incoming transaction data down and create the underlying table structures dynamically as new sources and volume grew. The same layer also supported dynamic reporting, allowing queries to target structures appropriate to the transaction type and requested time window rather than relying on generalized reporting tables.

Challenge 02
Sources that spoke different data languages

Hard-coding every source format would have made the platform difficult to maintain. Configurable mapping allowed the ingestion layer to adapt to new source schemas while the reconciliation engine continued working against one consistent internal model.

Challenge 03
Maintaining an audit trail

When reconciliation failed, an operator needed to know where the transaction originated, what transformations had been applied, whether it had already been processed, and why matching failed. Raw records therefore remained separate from the structured processed state.

Challenge 04
Protecting sensitive financial data

Card numbers and related financial information were encrypted before storage, with access controlled by user permissions. Security had to be part of the data model from the beginning rather than added after the fact.

Challenge 05
Reconciling more than amounts

A financial transaction isn't always just debit equals credit. The engine needed to understand relationships between the primary transaction, commissions, cash refills, retracts, and other operational events rather than comparing values alone.

Challenge 06
Getting from transaction to customer

The platform automatically identified the customer account related to a transaction, turning “this transaction failed reconciliation” into the more useful operational question: which customer and account were affected, and what should happen next?

At transaction scale, data movement becomes the architecture.

This project changed how I think about backend engineering. At smaller scale, a system can feel like a collection of endpoints, tables, and business logic.

At financial transaction volume, the questions that matter shift: how data moves through the system, how a transaction is processed exactly once, how it can be traced months later, and how the system adapts as external formats and transaction volume continue to change.

Good architecture here wasn't just about making the system work — it was about making sure it continued working as volume, integrations, and the cost of failure all increased. That's the lens I still bring to large-scale transaction-processing systems today.

Have something you'd like to build, improve, or solve?

I'm always open to conversations around interesting problems, ideas, and opportunities to work together.

Reach out at hi@riteshr.au